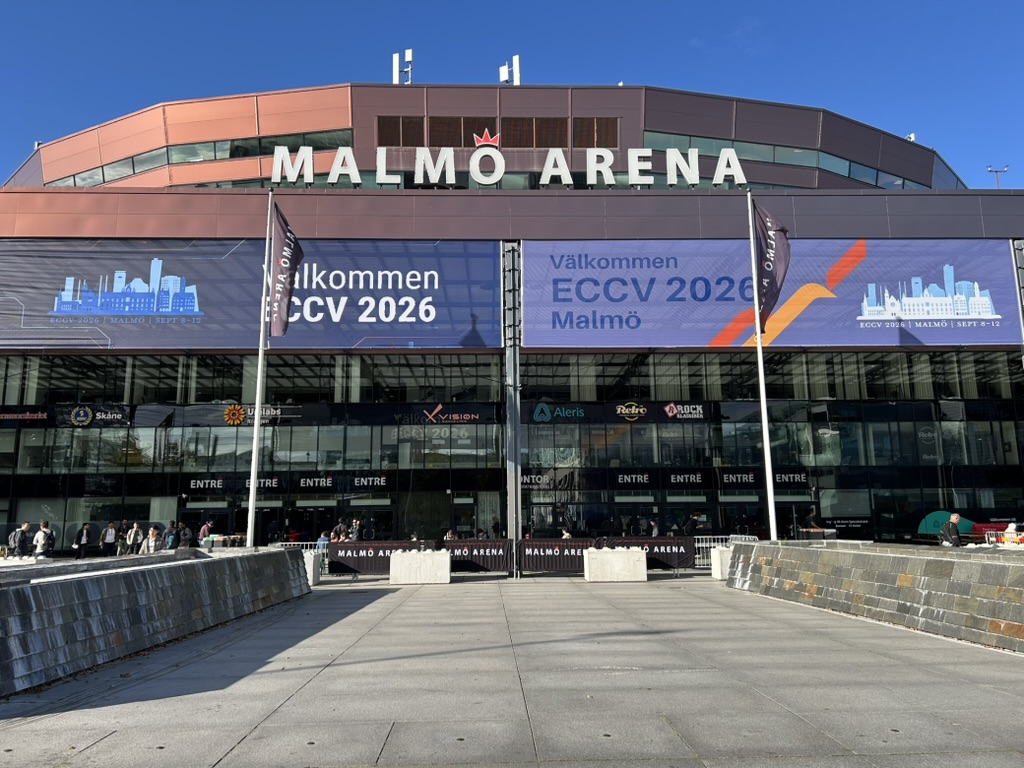
I recently attended the European Conference on Computer Vision (ECCV) 2026 in Malmo, Sweden and wanted to share some highlights from the research, workshops and discussions I participated in that are relevant for Eedi, and, I believe, for the broader edtech community.
The workshop on uncertainty quantification in machine learning models is very relevant for Eedi and our ongoing research. It also covered handling out of distribution data, which is something we deal with at Eedi when scaling to new markets. There was also work presented on the generated outputs of LLMs focusing on the language they use. They advocate for judging LLMs by human standards, arguing that LLMs should have anthropomimetic uncertainty in LLM generated content, but that LLMs should not anthropomorphise. This is very relevant for Eedi given our use of LLMs in production.
Data curation and improving our datasets is of importance for Eedi as we strive to build better models. This workshop presented a collection of interesting and different approaches in that area. There was a lot of work utilising large pre-trained models to act as a prior when operating in an area with limited training data. There was also a lot of discussion about evaluating how well LLMs can solve a specific task, which is a relevant approach for Eedi for building faster solutions for new tasks. Finally, there were also talks about efficient LLMs for resource constrained devices, which could be a relevant direction for Eedi in the future if cost becomes a significant factor in the use of LLMs for different markets.
I saw multiple research projects working on unlearning, the concept of training a model to not be able to understand certain data. This feels like relevant work for Eedi to explore in the area of student simulators given the concern that the underlying LLM models know all of the answers. There were also many interesting pieces of work around LLM safety showing novel approaches like using input images to improve the safety of LLM generated content. There seems also to be an increase in the amount of research related to more agentic approaches to using LLMs which I found interesting.